 Cloud & AI Infrastructure
 Cloud & Cyber Security Expo
 Big Data & AI World
 Data Centre World
Insights
How to Operate AI Infrastructure at Scale
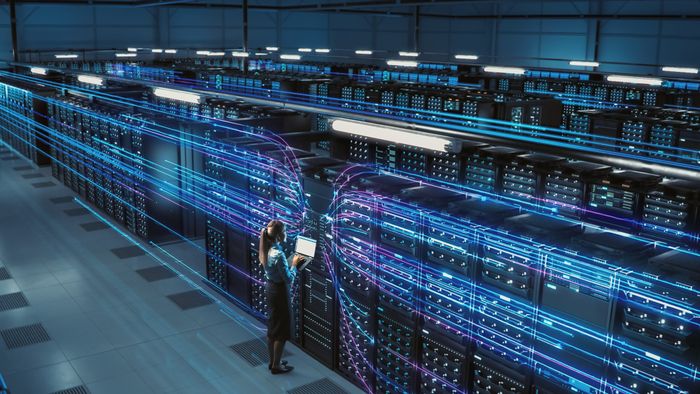
Operating AI infrastructure at scale is as much a data centre operations challenge as a software one. Once pilots become production services, chips, and code depend on a physical environment that must stay available under load. Teams need to commission, monitor, maintain, and recover that environment without disrupting the business.
The pressure is growing. The International Energy Agency projects that electricity generation to supply data centres will rise from about 460 TWh in 2024 to more than 1,000 TWh in 2030. Grid access and efficient use of power are therefore becoming day-to-day operating concerns.
Why AI Data Centre Infrastructure Is Different
A conventional enterprise data centre runs a broad mix of business systems, usually on CPU-based servers. An AI data centre concentrates GPUs or other accelerators in tightly connected systems that exchange large datasets at high speed.
That concentration changes the operating environment. Uptime Institute says the vast majority of racks remain below 10 kW. Current high-density AI systems can exceed 40 kW, and next-generation implementations can pass 100 kW. They need more electricity and faster networking, while generating much more heat in a small space. A single fault in cooling, networking, or power can interrupt an expensive group of interdependent machines.
Not every AI deployment reaches those densities. Large-model training generally creates the greatest infrastructure demands. Enterprise inference is often smaller, so operators should size the facility to the workload rather than assume every AI service needs the same design.
What Makes Up the AI Infrastructure Stack
GPU infrastructure extends beyond the accelerator itself. Compute nodes combine GPUs with CPUs, high-bandwidth memory and fast interconnects. Storage keeps data close to the cluster, while software schedules jobs, shares capacity, and monitors performance.
The facility below it must supply stable power, remove heat, and protect the equipment. NVIDIA's DGX BasePOD reference architecture illustrates the dependency: its compute nodes rely on separate networks for compute, storage and management, plus validated storage and cluster software. Buying GPUs before confirming the supporting infrastructure can leave costly hardware underused.
Power Density and Liquid Cooling
Cooling makes the shift visible. Uptime Institute puts perimeter air cooling at roughly 20 to 25 kW per rack and close-coupled air systems at up to 50 kW. Above that, direct liquid cooling typically becomes the preferred approach. Direct-to-chip systems move liquid through cold plates attached to components such as CPUs and GPUs. Immersion cooling places equipment in dielectric fluid; Uptime says it remains less frequently deployed and has yet to gain broad uptake for AI workloads.
Real-world systems show how quickly the requirements are changing. Google's 9,216-chip Ironwood TPU pod is liquid-cooled and spans nearly 10 MW. Microsoft has also run two-phase immersion cooling in a production data centre. These examples use different designs because cooling must follow the density, hardware and operating model.
Lawrence Berkeley National Laboratory (LBNL) reports that direct-to-chip cooling can reduce cooling-related energy use in heat-dense systems and help processors avoid thermal throttling. The trade-off is more equipment to operate, including pumps and coolant distribution units, plus leak detection and water-quality controls. Residual heat may still need air cooling.
How Teams Procure and Monitor AI Infrastructure
Responsibility may sit with an infrastructure director, data centre manager, or platform engineering lead working with procurement and facilities. The buyer first needs a realistic workload profile. Is the service for training or inference? How heavily will it run, where must the data remain, and how quickly could demand grow? Teams must then confirm available power, supported rack density, cooling compatibility, expansion space, and the delivery date for any grid connection. Commissioning should test that complete chain under realistic load.
Once live, monitoring should join facility and IT data. Operators need to see power draw and thermal conditions alongside GPU utilisation, network congestion, storage performance, and job failures. LBNL notes that AI workloads can change power demand rapidly, making real-time readings and useful alert thresholds essential. Monitoring tools only help when teams also have clear escalation routes, spare parts, and rehearsed recovery procedures.
How Colocation Supports Data Centre Operations
Colocation means placing an organisation's own hardware in a third-party data centre. As Equinix explains, the operator provides the space and shared infrastructure; the customer retains control of its servers. This can avoid the time and capital needed to build a dedicated facility. An "AI-ready" label, however, is not proof that a site fits the workload.
Buyers should ask for evidence of committed power, not headline capacity. They should also verify cooling at the planned rack density, room to expand, access to monitoring, and the scope of remote-hands support. Uptime Institute's cooling guidance warns that direct liquid cooling can blur service-level boundaries between facility teams and tenants. Responsibilities for coolant loops, leak alarms, maintenance, and emergency shutdowns should therefore be agreed before installation.
Data centre resilience depends on the full operating environment. The useful measure is how much compute the organisation can deliver consistently within its cost, power and cooling limits. Teams that involve data centre operators early and rehearse failures against a shared capacity plan are better placed to turn AI investment into a dependable business service.
Research Sources
• International Energy Agency Energy supply for AI
• Uptime Institute Intelligence AI and cooling methods and capacities
• Lawrence Berkeley National Laboratory Computational Hardware and Benchmarking
• NVIDIA Enterprise AI Reference Architecture for DGX BasePOD
• Google Ironwood TPU for the age of inference
• Microsoft To cool datacenter servers, Microsoft turns to boiling liquid
• Uptime Institute Intelligence DCIM Procurement Guide 2026
• ASHRAE Emergence and Expansion of Liquid Cooling in Mainstream Data Centers